Web data field notes
Practical guides for fetching, rendering, crawling, and shaping public web data for production systems.
22 field notes
Newest first
Best Reddit Scraper in 2026
Compare PRAW, Apify Trudax and SpideyData for Reddit collection. Dated documentation checks, deprecation status and recommendations by task.
How to Export Reddit Comments to CSV
Step-by-step: export comments from a public Reddit thread to CSV using a free tool, then scale with the Comments API when you need depth or automation.
How to Get Reddit Comments with an API
Developer guide: fetch public Reddit comment trees with sync GETs, then use async comment jobs when you need deeper collection.
How to Monitor a Subreddit with an API
Build a subreddit new-post monitor with a JSON API: create a monitor, run checks, and read events—distinct from brand-mention SaaS tools.
Reddit API vs PRAW
Compare using a managed public Reddit data API versus PRAW with official OAuth: language flexibility, ops burden, and what each cannot do.
Reddit API Without OAuth: What's Actually Possible
Reddit's official API uses OAuth. Here is what you can and cannot do without setting up your own OAuth app—public read-only options, their limits, and when you still need OAuth.
Reddit Community Search
How to search Reddit communities and subreddits for research. Includes using a communities search API for public discovery—not an archive or user-investigation tool.
Scrape Reddit Without the Official API
How to get public Reddit data without building your own Reddit OAuth app—free tools and managed Bearer APIs explained, with honest limits.
How to Scrape Reddit
Learn practical ways to scrape public Reddit data in 2026—free tools, managed APIs, and boundaries you should not cross (private, deleted, write actions).
Web Scraping vs API: How Engineers Should Choose Between Official APIs, Scrapers, and Web Data APIs
Compare web scraping vs API approaches for data collection, including official site APIs, DIY scraping, and documented web data APIs. This outline helps engineers evaluate access, structure, change risk, rate limits, and cost framing, with a brief introduction to SpideyData’s confirmed Fetch, Browser, Crawl, Extract, Runs, and Credits model.
Best Web Scraping API: How Technical Buyers Should Evaluate Options
A practical buyer’s guide for evaluating web scraping APIs without rankings. Learn how to compare fetch, rendering, crawl, extraction, credits, auth, docs, and scope boundaries, with a brief introduction to SpideyData’s confirmed capabilities.
Web Scraping API Buyer Guide: What to Check and How SpideyData Fits
Evaluate a web scraping API with practical criteria: fetch vs browser vs crawl vs extract, credit-based pricing, docs, auth, and rate-limit signals. See how SpideyData Web Data API (kieapi.com) fits based on confirmed public capabilities and pricing.
How Cloudflare Challenges Work: From Risk Signals to Turnstile Verification
How Cloudflare evaluates risk, runs Managed Challenges and validates Turnstile tokens, with the difference between tokens and clearance cookies.
ChatGPT dots Website Access: IP Checks and API Options
Troubleshoot website access in ChatGPT dots, check its exit IP, and explore SpideyData APIs for retrieving the web content your research needs.
Bot Detection Judges the Whole Session, Not a Single Fingerprint
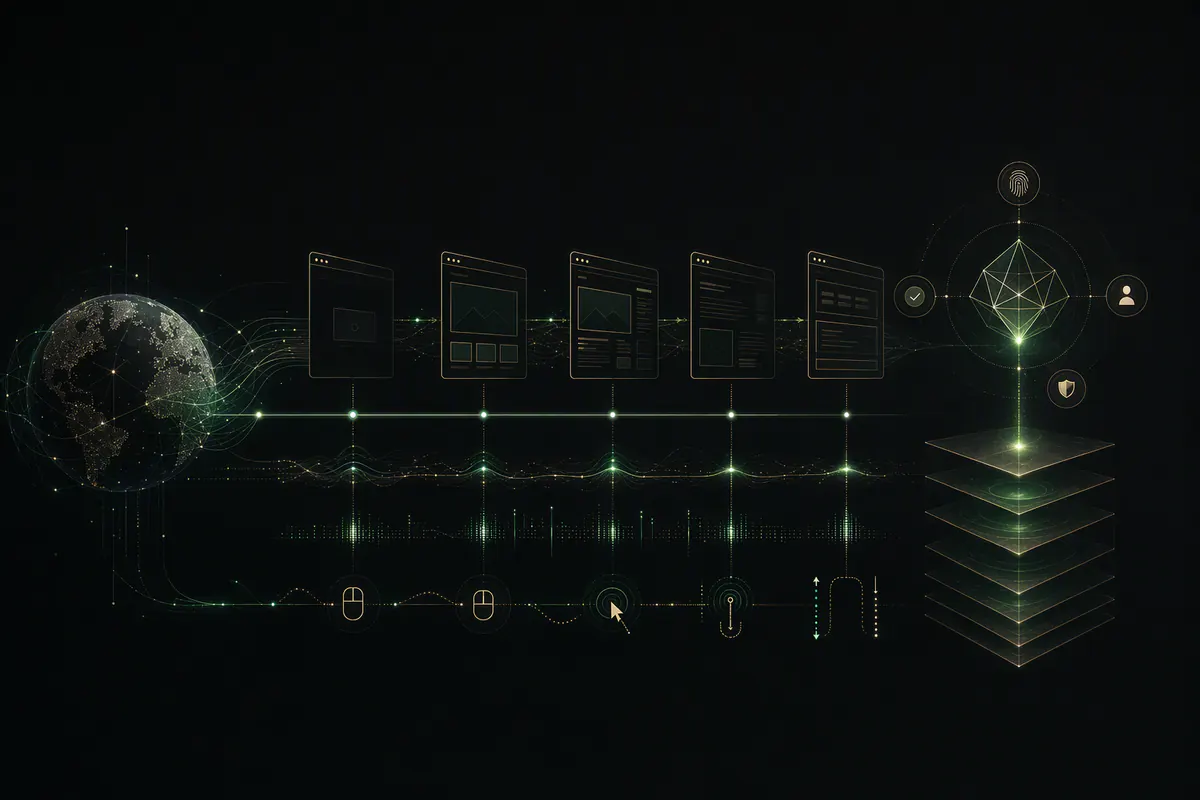
Modern defenses correlate network identity, navigation, interaction, resource timing, and session history instead of trusting one browser fingerprint.
Browser Fingerprinting Is a Consistency Audit, Not a Checklist
Canvas, WebGL, audio, clean realms, WebAssembly, storage, and automation traces become meaningful when they are evaluated as one device story.
Bot Detection Starts Before HTTP
Public docs describe TCP, TLS, HTTP/2, headers, and QUIC as layered client signals; our owned fixture measured only forced HTTP/1.1 application headers—not TLS/JA3 or other pre-HTTP layers.
Before You Add a CAPTCHA, Map Every Data Exit
The cheapest path to valuable data is often an under-protected API, search route, export, preview, or legacy surface—not the hardened web page.
Modern Bot Defense Is an Identity Consistency Problem
Why modern defenses correlate network, browser, device, behavior, and reputation signals—and what responsible web data teams should learn from that design.
POST /v1/browser/scrapeWhen a web data request needs a browser
A practical way to choose between direct fetch and browser rendering without paying browser cost for every page.
POST /v1/crawlDesigning bounded crawls for production
Define scope, depth, and result ownership before a crawl starts so asynchronous collection stays predictable.
POST /v1/extractFrom HTML to structured data for agents
Separate acquisition from extraction, then validate a typed result before it becomes agent context.
SERP API guides
17 guides to the SpideyData SERP API, alternatives and adjacent search APIs.
- SERP API guide
Google Custom Search API Alternative: When a Live SERP Fits Better
Google's Custom Search JSON API searches an index you configure; a SERP API fetches the live results page. How to decide, and how to migrate one call.
- SERP API guide
How to Scrape Google SERP in 2026 (and When to Stop)
A practical 2026 walkthrough: what DIY scraping of Google results involves (blocks, parsing, ToS risk), then the same job as one POST to a managed SERP endpoint.
- SERP API guide
How to Get Google Search Results as JSON
Get Google results as structured JSON: request body, response fields like organic[], rank and organic_count, which fields can be null, and how this differs from the Custom Search JSON API.
- SERP API guide
Best SERP API 2026: A Buyer's Scorecard
A 2026 SERP API scorecard: compare providers by engines covered, async model, output format and pricing basis, with SpideyData listed honestly. Baidu and Ecosia endpoints opening soon. Not GA.
- SERP API guide
SERP API Pricing Comparison: How Each Provider Meters
Compare how SERP APIs charge: per search, per credit or per request, free tiers and what counts as billable. SpideyData shows a display price of 2 Credits per successful search.
- SERP API guide
SERP API vs Google Custom Search
A side-by-side table of a live SERP API and Google's Custom Search JSON API: data source, engines, locale params, async, billing basis. No invented quotas.
- SERP API guide
How to Use the SERP API: Auth, Idempotency, Sync vs Tasks
Step by step: authenticate with a Bearer key, add an Idempotency-Key, call sync endpoints, or create a Google task (202) and poll it. Error codes explained. No webhooks.
- SERP API guide
Build a Rank Tracker with a SERP API
Build your own rank tracker: queue Google organic tasks per keyword, poll results, match your domain in organic[], and store daily positions in SQLite. You run the scheduler.
- SERP API guide
Web Search API vs SERP API: Which Does Your App Need?
"Web search API" covers LLM-oriented search tools and raw SERP APIs. This guide explains the difference and when ranked SERP JSON from /v1/serp is the right fit.
- SERP API guide
Yandex SERP API: What SpideyData Covers Instead
SpideyData's SERP API does not include Yandex. Yandex offers its own Search API (XML/HTML); here's how that differs and which engines /v1/serp does cover.
- SERP API guide
Google Maps SERP API: Outside the /v1/serp Scope
Map pack and Maps listings are not returned by SpideyData's /v1/serp endpoints, which return organic, news and images only. What to use instead, and how not to confuse the two.
- SERP API guide
Google Shopping SERP API: Not a SpideyData Vertical
There is no Shopping vertical in SpideyData's SERP API. Google's Content API for Shopping is deprecated in favor of Merchant API (for your own products). Here's what each is for.
- SERP API guide
SERP API SLA: What to Ask a Provider
What an SLA for a SERP API should define, the questions buyers ask, and SpideyData's honest status: no published SLA or success-rate figures. Baidu and Ecosia endpoints opening soon. Not GA.
- SERP API guide
Is There an Unlimited SERP API?
"Unlimited" SERP plans usually hide caps elsewhere. SpideyData is metered: a display price of 2 Credits per successful search, plus platform rate limits. No unlimited tier.
- SERP API guide
Google Search Console API Alternative? What a SERP API Can and Can't Replace
A SERP API is not a Search Console replacement. GSC reports your site's clicks, impressions and indexing; a SERP API shows public result positions for any keyword.
- SERP API guide
"SEOAPI SERP": Which Endpoint Do You Mean?
If you searched "seoapi serp", you may mean the SerpApi brand, a legacy seoapi adapter path, or SpideyData's Pure SERP API at /v1/serp. This page routes you to the right one.
- SERP API guide
Semrush SERP API vs a Pure SERP API
Semrush's API serves SEO-suite data such as positions, SERP features and traffic. SpideyData's /v1/serp returns raw organic, news and images rows. How the two differ, and when you need which.