Engineering
Design notes for bounded, explainable collection systems.
12 field notes
Newest first
Web Scraping vs API: How Engineers Should Choose Between Official APIs, Scrapers, and Web Data APIs
Compare web scraping vs API approaches for data collection, including official site APIs, DIY scraping, and documented web data APIs. This outline helps engineers evaluate access, structure, change risk, rate limits, and cost framing, with a brief introduction to SpideyData’s confirmed Fetch, Browser, Crawl, Extract, Runs, and Credits model.
Best Web Scraping API: How Technical Buyers Should Evaluate Options
A practical buyer’s guide for evaluating web scraping APIs without rankings. Learn how to compare fetch, rendering, crawl, extraction, credits, auth, docs, and scope boundaries, with a brief introduction to SpideyData’s confirmed capabilities.
Web Scraping API Buyer Guide: What to Check and How SpideyData Fits
Evaluate a web scraping API with practical criteria: fetch vs browser vs crawl vs extract, credit-based pricing, docs, auth, and rate-limit signals. See how SpideyData Web Data API (kieapi.com) fits based on confirmed public capabilities and pricing.
How Cloudflare Challenges Work: From Risk Signals to Turnstile Verification
How Cloudflare evaluates risk, runs Managed Challenges and validates Turnstile tokens, with the difference between tokens and clearance cookies.
ChatGPT dots Website Access: IP Checks and API Options
Troubleshoot website access in ChatGPT dots, check its exit IP, and explore SpideyData APIs for retrieving the web content your research needs.
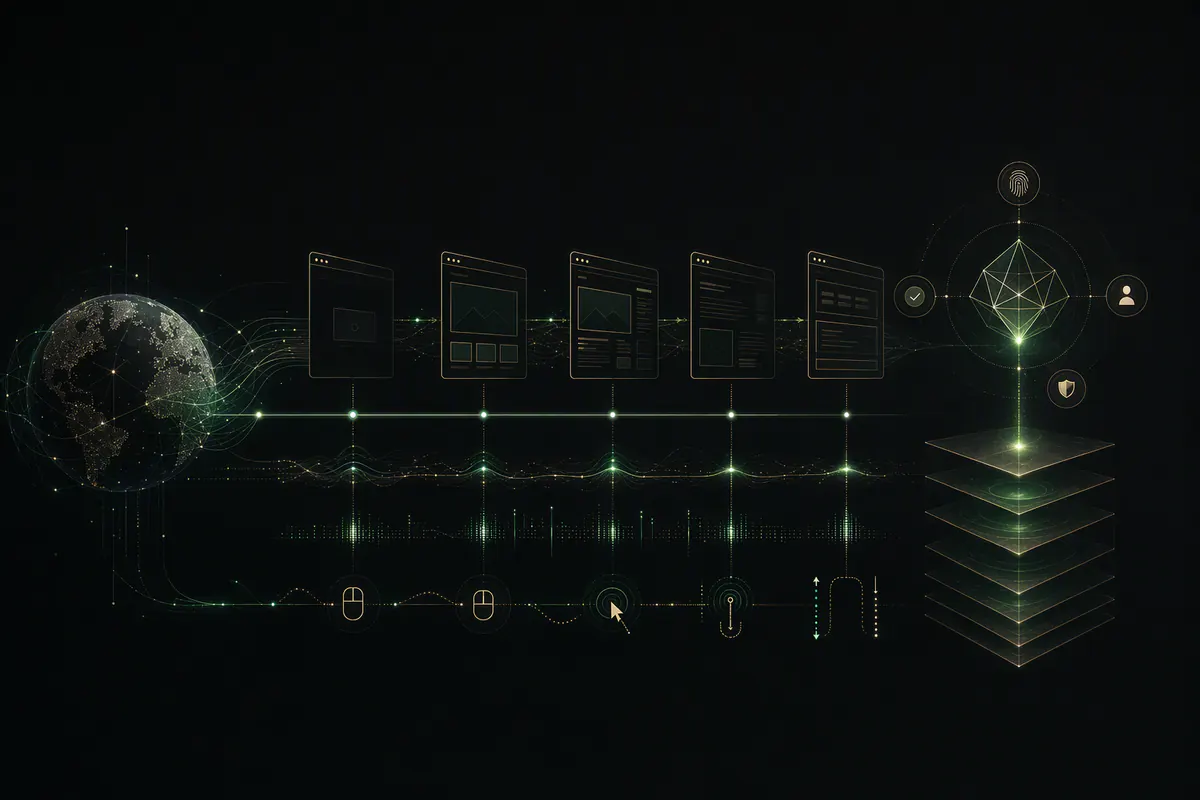
Bot Detection Judges the Whole Session, Not a Single Fingerprint
Modern defenses correlate network identity, navigation, interaction, resource timing, and session history instead of trusting one browser fingerprint.
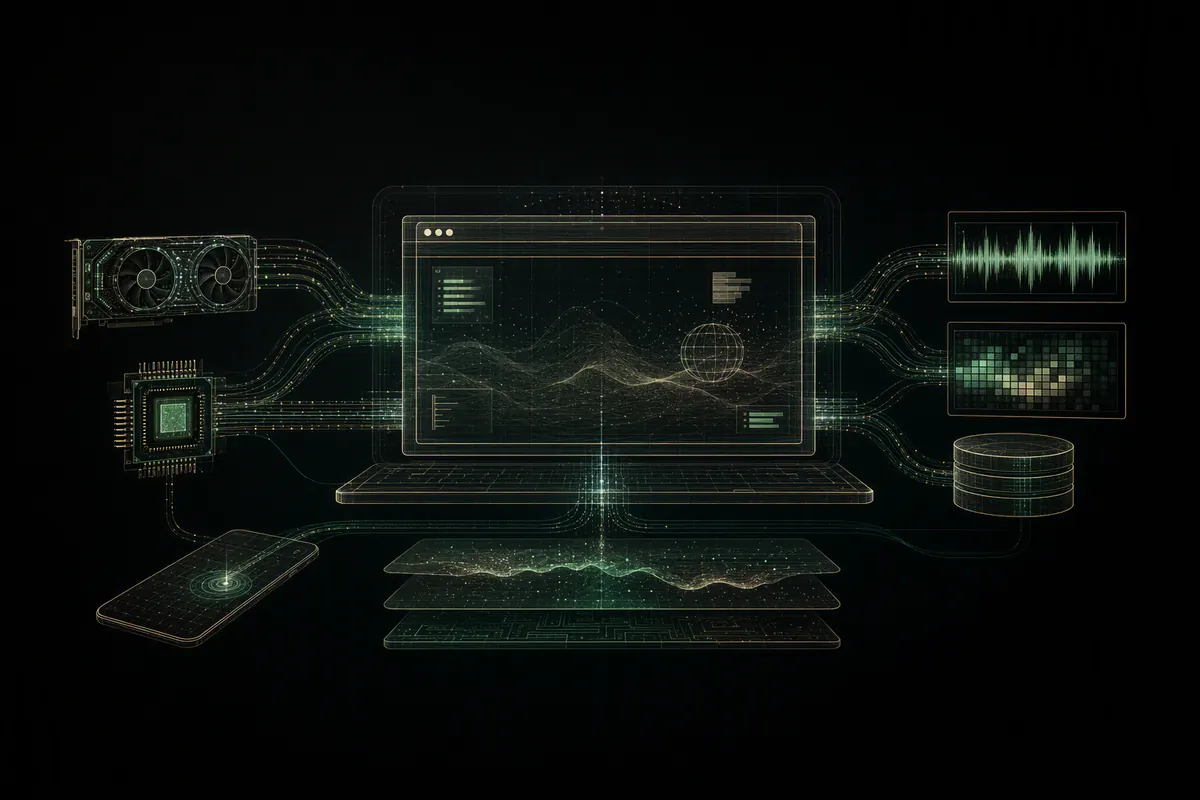
Browser Fingerprinting Is a Consistency Audit, Not a Checklist
Canvas, WebGL, audio, clean realms, WebAssembly, storage, and automation traces become meaningful when they are evaluated as one device story.
Bot Detection Starts Before HTTP
Public docs describe TCP, TLS, HTTP/2, headers, and QUIC as layered client signals; our owned fixture measured only forced HTTP/1.1 application headers—not TLS/JA3 or other pre-HTTP layers.
Before You Add a CAPTCHA, Map Every Data Exit
The cheapest path to valuable data is often an under-protected API, search route, export, preview, or legacy surface—not the hardened web page.
Modern Bot Defense Is an Identity Consistency Problem
Why modern defenses correlate network, browser, device, behavior, and reputation signals—and what responsible web data teams should learn from that design.
POST /v1/browser/scrapeWhen a web data request needs a browser
A practical way to choose between direct fetch and browser rendering without paying browser cost for every page.
POST /v1/crawlDesigning bounded crawls for production
Define scope, depth, and result ownership before a crawl starts so asynchronous collection stays predictable.