Modern Bot Defense Is an Identity Consistency Problem
Why modern defenses correlate network, browser, device, behavior, and reputation signals—and what responsible web data teams should learn from that design.
The fingerprint misconception
Browser fingerprinting is often described as a checklist: user agent, screen size, fonts, canvas output, WebGL renderer, and a few automation flags. That model is useful for explaining individual signals, but it misses how modern bot defense systems make decisions.
A production defense rarely asks whether one fingerprint looks real in isolation. It asks whether every observation belongs to the same plausible identity, whether that identity remains coherent across a session, and whether its history resembles legitimate use on this particular application.
That changes the problem from copying values to maintaining consistency. A convincing header set cannot repair a contradictory network handshake. A realistic browser runtime cannot erase impossible timing, abrupt identity changes, or a reputation history associated with abusive traffic.
Identity is a stack, not a field
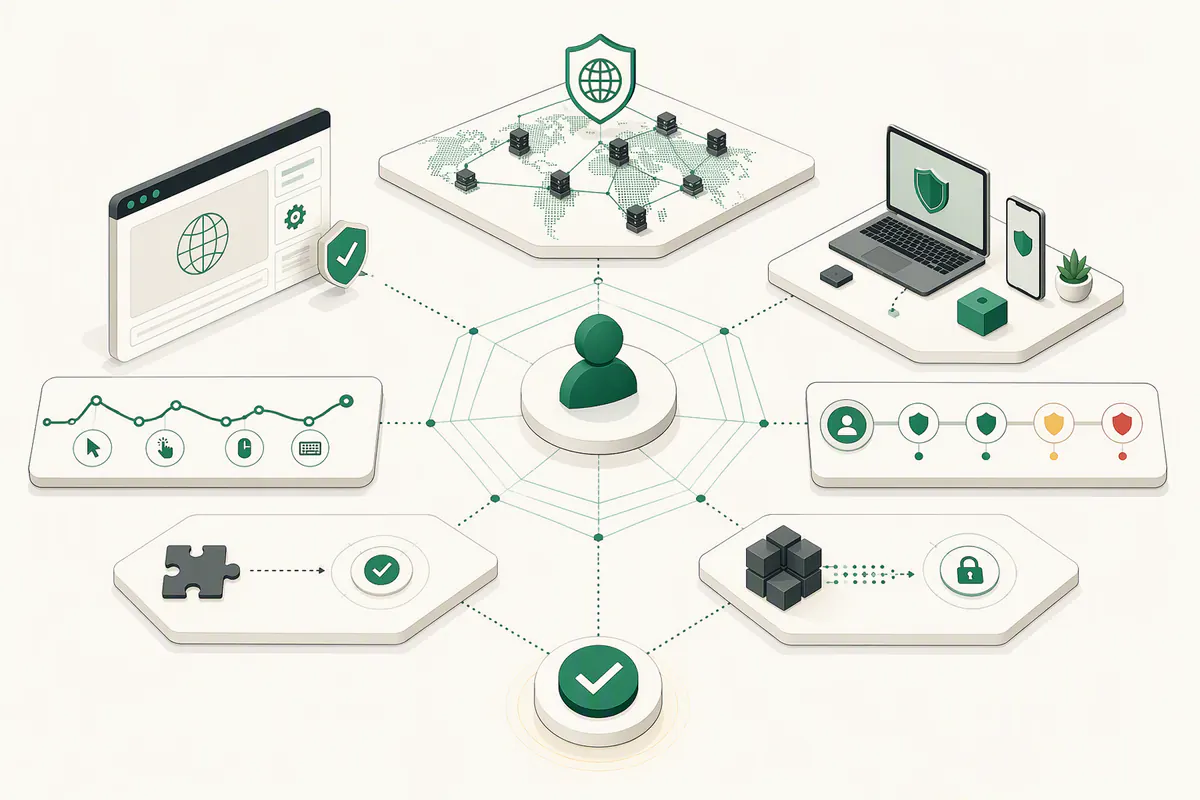
The useful mental model is a layered identity stack. Each layer contributes evidence, and the relationships between layers often matter more than any single value.
- Network and transport: IP reputation, autonomous system, connection reuse, TLS characteristics, and the shape of the handshake.
- Protocol and request: HTTP version, header ordering and consistency, cookies, navigation context, and request cadence.
- Browser runtime: JavaScript APIs, DOM and BOM behavior, rendering capabilities, extension or plugin signals, and signs of environment modification.
- Device environment: screen and graphics properties, locale and time zone, input capabilities, storage state, and other features expected to move together.
- Behavior and session: navigation sequence, interaction timing, repeated actions, state continuity, and whether the session develops like a real visit.
- Reputation and application context: prior outcomes, known automation signatures, route sensitivity, and behavior calibrated to a specific site.
Different products place the gate in different layers
The best-known vendors do not all defend the same way. Their public documentation describes overlapping signals, but their product boundaries reveal different places where they prefer to observe, score, and enforce.
Edge-native platforms such as Cloudflare and Fastly can combine request and protocol context with client-side detections and challenges close to the network edge. Akamai Bot Manager and HUMAN Bot Defender describe broad signal collection across requests, browsers, devices, and behavior, followed by risk scoring and policy enforcement.
Other products emphasize application-calibrated device and behavioral analysis or client-integrity and challenge-heavy controls. Those categories are more useful than a winner-takes-all ranking: a checkout flow, a media site, and a public documentation portal have different risk, latency, and user-experience constraints.
Anubis makes the economic idea especially visible. It can issue client challenges—including proof-of-work—to impose a small cost before an upstream resource is served. The project is explicit that this is not magic; the goal is to make indiscriminate automated traffic more expensive while allowing operators to define exceptions.
Consistency beats isolated realism
A single signal is noisy. Real users have unusual extensions, privacy settings, corporate proxies, accessibility tools, and imperfect networks. Reliable defenses therefore correlate weak observations instead of treating one anomaly as proof.
Contradictions become useful when they accumulate. A modern browser claim paired with an implausible transport profile, a device identity that changes halfway through a session, or perfectly regular activity with no credible navigation history can lower confidence even when each individual value passes a superficial check.
This is also why copying a visible fingerprint report is not a durable strategy. The report shows what one script can observe at one moment. A defense can observe other layers, compare them over time, and tune the decision to the protected application.
Anti-bot is an economic system
The practical objective is not to solve the philosophical question of whether a visitor is human. It is to control abuse while preserving access for legitimate users, verified crawlers, partners, and APIs.
A defense succeeds when unwanted automation becomes slower, less stable, harder to scale, and more expensive to maintain. Challenges, rate controls, reputation, session continuity, and application-specific models are different ways of changing that cost curve. The right response may be allow, monitor, slow down, challenge, or block—not a universal denial.
What responsible web data teams should learn
For legitimate collection, the lesson is not to imitate every signal. It is to make the collection path explicit, bounded, and compatible with the publisher's rules. A browser is a rendering tool, not permission to bypass an access decision.
- Prefer an official API, feed, export, or verified-bot path when the publisher provides one.
- Respect robots directives, terms, authentication boundaries, and route-specific rate limits.
- Start with a direct fetch for permitted public content; use browser rendering only when JavaScript or interaction is genuinely required to obtain that content.
- Treat a challenge, login wall, or explicit denial as a policy signal. Stop or escalate for authorization instead of silently turning it into a bypass project.
- Use stable identification, conservative concurrency, caching, and incremental refreshes to reduce load on the source.
Make every escalation explainable
An operational collection system should preserve the evidence behind each decision: which engine was attempted, why a direct fetch was accepted or rejected, whether browser rendering was required, what quality signals were observed, how much the attempt cost, and which identity or profile was used when that data is available.
This audit trail separates content acquisition from guesswork. It helps teams distinguish a JavaScript application shell from a security challenge, a temporary rate limit from a permanent policy boundary, and a low-quality extraction from a network failure. It also makes it possible to improve routing without normalizing increasingly aggressive retries.
Modern bot defense is built around correlated identity. Responsible web data infrastructure should answer with correlated evidence: the smallest permitted path, a clear reason for every escalation, and a durable record of what happened.
Sources and further reading
Try the smallest path that fits your target
Start with the public Fetch guide, then add browser rendering, crawling, or extraction when the workflow needs it.